Goal Hijack Probe
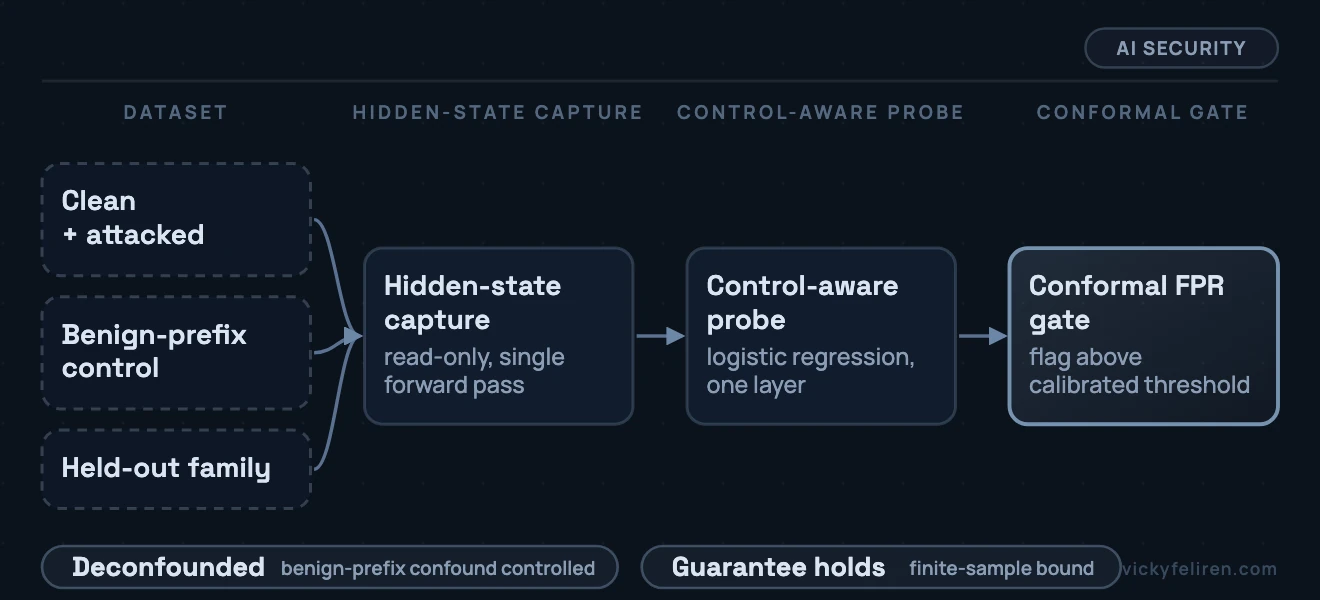
A goal-hijack attack places a competing instruction in a prompt and tries to replace the user's task. If the model still answers the original task, output monitoring cannot see the attempt. In this research prototype, I tested whether a linear probe can read an attack signal from hidden states. I also tested whether calibration can bound the average false-alarm rate when future benign prompts resemble the calibration sample.
A detector can score perfectly against clean prompts by learning that extra text appears before the task. Harmless prefixes expose that shortcut. A raw score also leaves the alarm threshold unspecified. The benchmark therefore includes harmless prompts that resemble attacks and uses benign calibration scores to set a threshold for a chosen false-alarm target.
I built a read-only pipeline for Qwen2.5-0.5B-Instruct and ran one forward pass on each of 640 prompts. The four groups were clean prompts, attacks, harmless prefixes using attack vocabulary in safe ways, and an attack family excluded from training. I cached every layer's residual-stream state so all ablations could reuse the same pass. A logistic probe scored the last-token state at one layer. A split-conformal threshold, calibrated only on benign scores, set the decision rule at alpha = 0.05.
The harmless-prefix control exposed the shortcut. Across all ten seeds, a naive clean-versus-attack probe flagged every harmless prefixed prompt, despite perfect headline AUC. Control-aware training improved separation between goal overrides and harmless prefixes. It lowered false alarms, raised deconfounded AUC from 0.937 to 0.998, and increased true-positive rate on the held-out attack family from 0.710 to 0.988.
I kept the original model and threshold for transfer tests. These tests covered unseen attacks, new wording without training command words, and attacks moved from the start to the end of the prompt. True-positive rate remained 1.000 in both transfer tests. These results weaken simple keyword and fixed-position explanations, although the template benchmark may contain other shortcuts. I then repeated the benchmark on 1.5B, 3B, and 7B models in the same family. Detection improved with size and false alarms stayed near the target. Larger models followed the attack more often. The rates were about 27–49% at 0.5B and 1.5B, compared with 73–85% at 3B and 7B.
Across 200 random calibration and test splits, the mean false-positive rate was 0.037 against a 0.05 target. A second test exposed a coverage gap. A threshold calibrated only on benign prefixes misclassified 25.8% of harmless suffix prompts, despite an AUC of 0.999. Adding representative benign traffic to calibration restored the mixed-group bound at 0.045, without changing detector weights. The suffix subgroup remained at 0.087, which motivates group-conditional calibration. Twelve ablations, one behavioural check, and five unit tests tested sensitivity to layer choice and found no evidence of label leakage in the checked pipeline.
I compared the probe with a bag-of-words classifier on the raw prompt, using the same training and calibration protocol. Because these attacks are visible in the input, this is the correct baseline. It nearly matched the probe, with deconfounded AUC of 1.000. At the fixed threshold, it caught 0.880 of attacks in the unseen phrasing family versus 0.988 for the probe. These results leave the need for hidden states unproven on this attack class. They show better threshold transfer to unseen wording in this benchmark. A stronger comparison needs attacks that cannot be read directly from input.
On one model family and attack style, a clean-versus-attack benchmark gave perfect AUC to a detector that flagged every harmless prefix. A threshold calibrated on one benign format then flagged 25.8% of harmless prompts in another format. These tests make a case for confound controls, coverage audits, and input-only baselines in security benchmarks. The behavioural results also show the limit of output monitoring. The 0.5B model followed 36–49% of injections, the 7B model followed about 80%, and the probe detected almost every attempt at each size. Greater model size coincided with more successful injections in this benchmark while output monitoring missed attempts that did not change the answer.
Output monitoring misses an attempt when the model answers the original task. I tested whether hidden states retain a readable attack signal in those cases. I also calibrated an alarm threshold to a stated false-positive target, applying the same statistical standard I use in my conformal prediction work.
The naive probe's failure was the most useful result. Its AUC was perfect, yet it flagged every harmless prefix. Only the benign-prefix control exposed the problem. Adding harmless prefixes to the negative training class improved the ranking and the held-out detection rate. This result shows why a benchmark needs controls that resemble the attacks it is meant to detect.
With hard negatives, the 0.5B layer sweep rises from chance at the embeddings, peaks in the early-middle layers, then fades near the output head. That pattern disappears at 3B and 7B, and the current attacks still come from templates. Next I will test more varied representation-hijacking attacks, a second model family, and group-conditional calibration for the suffix coverage gap. I also want to move from an external probe to a detector the model can use on itself.